When you hear that an AI model is "open source," you probably picture something like Linux: open code, free community, no corporate locks. In the world of LLMs, however, that word gets thrown around with a generosity that borders on dishonesty. According to the updated ranking at lmmarketcap.com, the vast majority of models marketed as "open source" are, technically speaking, anything but. They release the model weights—that massive file that was already trained—but hide the training code, data pipelines, and evaluation suites. It's like handing you the keys to a house without telling you how it was built or what materials were used. You can live there, but you can't replicate it.
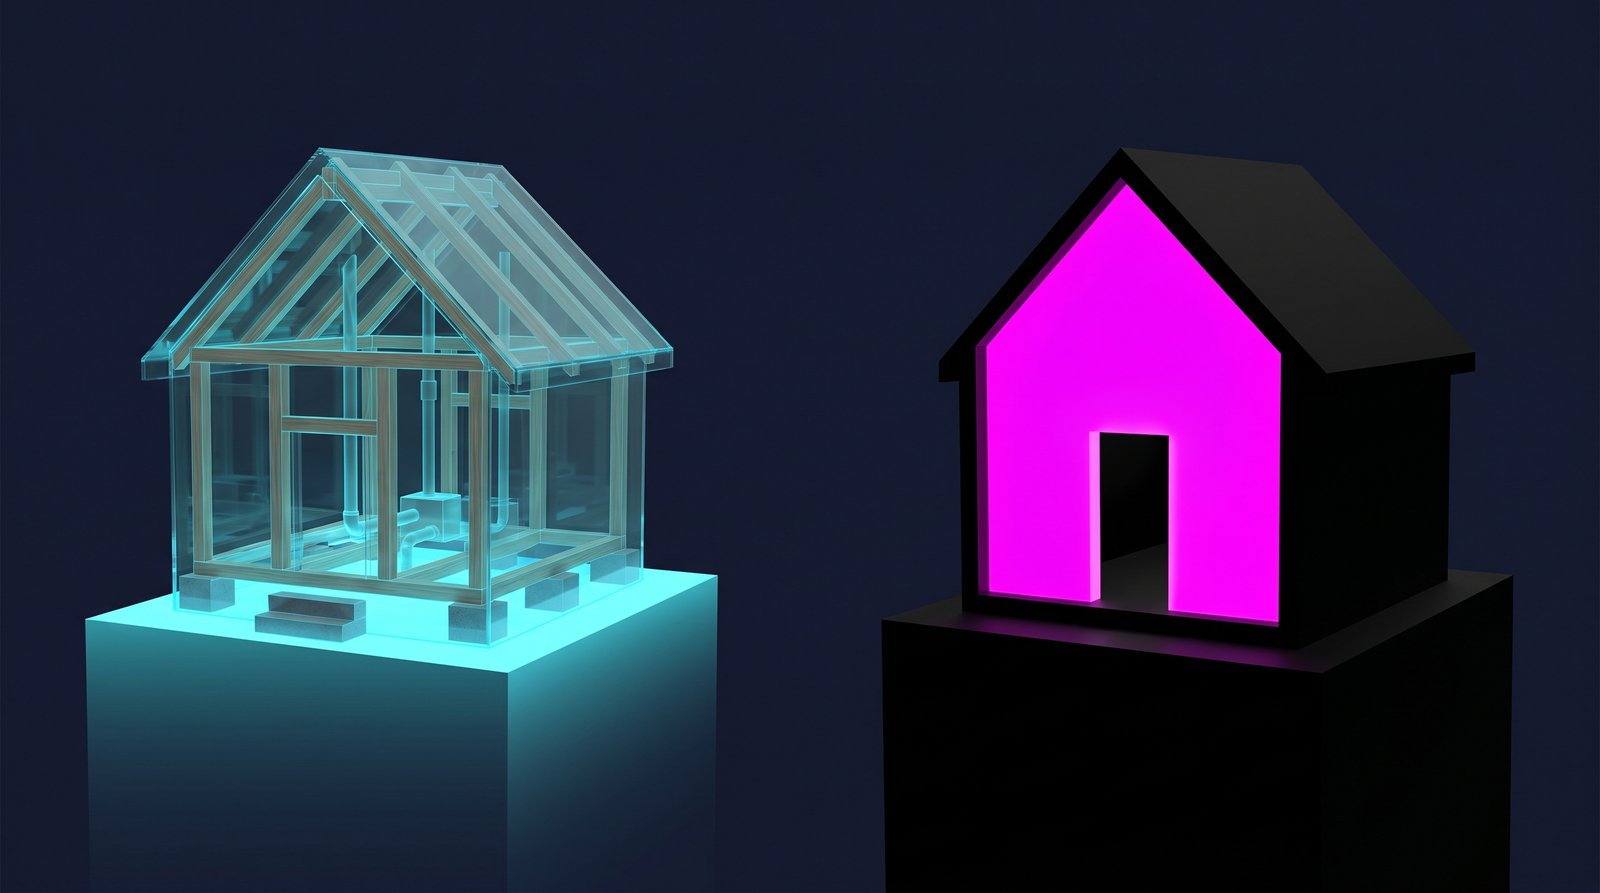
The distinction nobody explains to you
There's a brutal difference between "open weights" and truly "open source." Models that are genuinely open source release the entire stack: weights, training code, data pipelines, and evaluation methodologies, all under permissive licenses. Examples that fully meet this definition are extremely rare. Allen AI's OLMo is one of the few that has published absolutely everything. Meta's Llama, Mistral, Google's Gemma, Falcon—all fall into the "open weights" category: you can use the resulting model, but you can't reproduce the process from scratch because you don't have access to the training data or the complete code that generated it.
This isn't a minor technical detail. It's a distinction with enormous implications for the industry, for independent researchers, and for anyone who wants to audit these systems for biases, vulnerabilities, or simply to understand what they're doing with your data when you integrate them into an application.
The business behind "openness"
Big companies figured out quickly that releasing a model's weights generates an obscene amount of goodwill in the tech community. Meta's Llama generated more positive coverage through its "openness" than any other initiative in years. But let's be clear: releasing only the weights is a calculated business decision, not an act of altruism. They give you just enough to build on their architecture, generate use cases that validate their research, and create dependency on their ecosystem. The real control—how it was trained, on what data, under what conditions—stays inside.
The lmmarketcap.com leaderboard attempts to bring order to this chaos by ranking models according to how truly open they actually are. And the picture is revealing: in 2025–2026, with all the noise around DeepSeek, Qwen, Llama 3, Mistral, and company, the models that meet the full open source standard are an absolute minority. The rest use the label as a marketing tool.
What this means for anyone building with AI
If you're a developer, a music producer integrating AI into your workflow, or anyone embedding these models into real projects, the distinction matters on several levels. First, reproducibility: if you find strange behavior or a problematic bias in the model, without access to the training process you can't understand where it comes from or how to fix it. Second, sovereignty: an open weights model is still intellectual property of whoever trained it; usage licenses can change—and they have changed, as we saw with earlier versions of Llama—leaving entire projects in legal limbo. Third, security: auditing an AI system without access to the full pipeline is like reviewing the safety of a building without blueprints.
The genuine open AI movement exists and is valuable. Allen AI, EleutherAI, and some community projects are doing the real heavy lifting. But they're the exception, not the rule, and the ecosystem needs to start calling things by their proper names. "Open weights" is open weights. "Open source" is something else entirely. As long as the industry continues using both terms as synonyms, the lmmarketcap.com leaderboard—and similar resources—become essential tools for navigating the noise without getting sold a fake.
The conversation about how "open" open AI really is has barely started, and in 2026 it's going to become much more urgent as more critical infrastructure gets built on top of these models. Knowing exactly what you have in your hands—and what you don't—isn't an academic luxury. It's an operational decision.